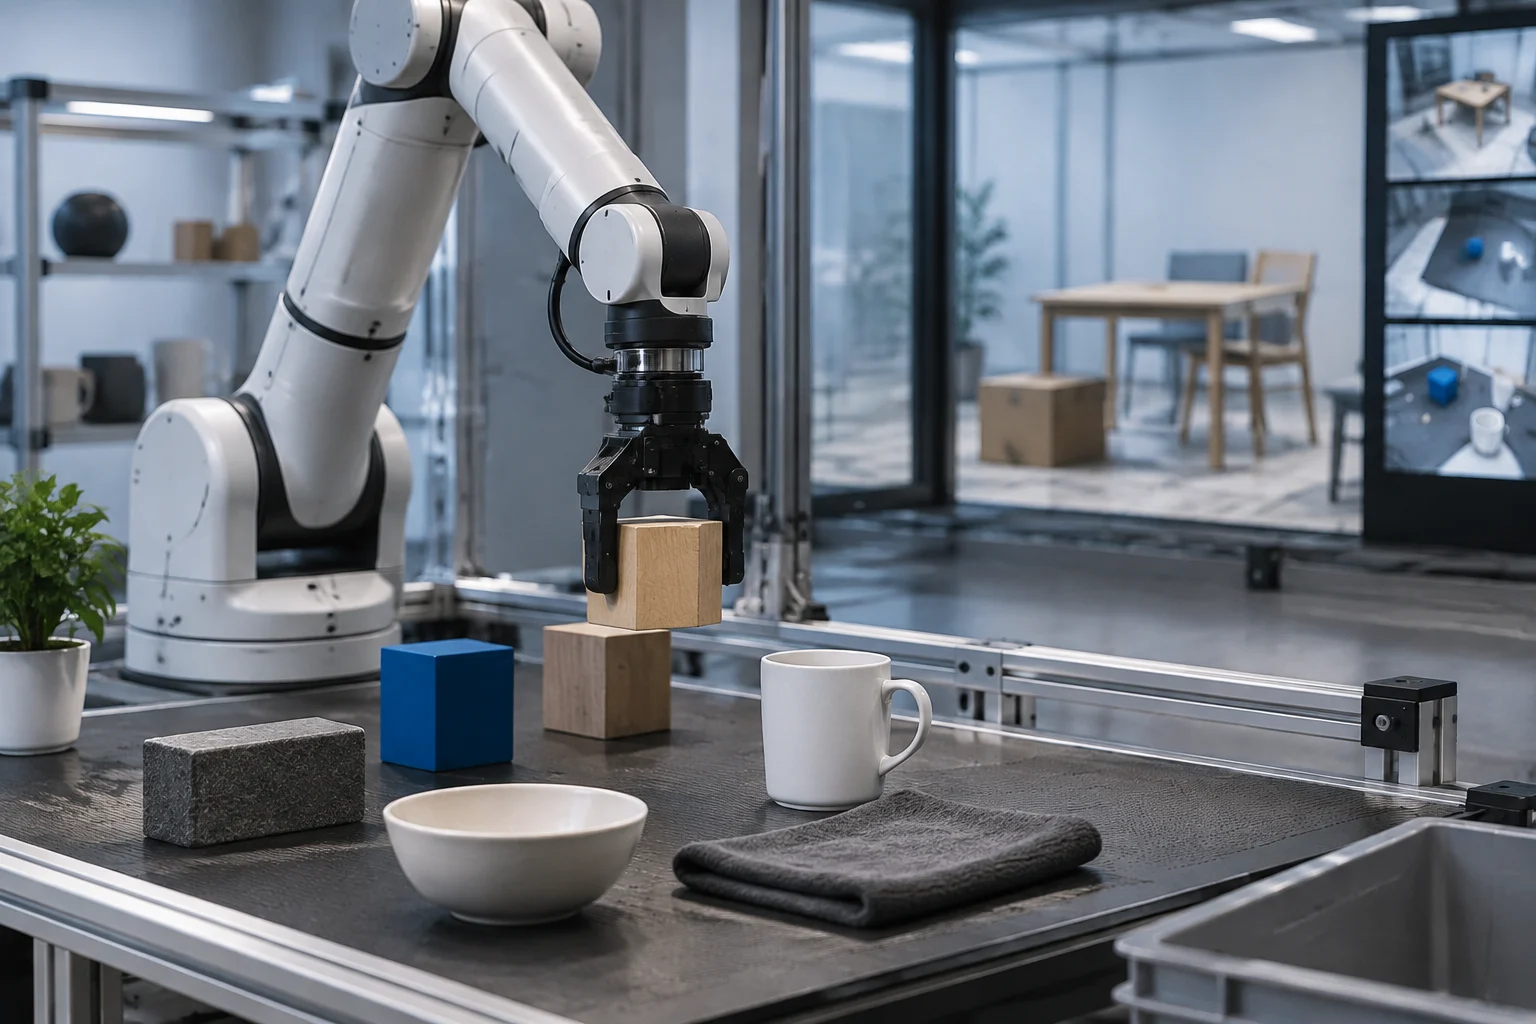
A score answers a narrowly defined question
A benchmark organizes an evaluation around specified tasks and conditions. Its score describes the outcome achieved within that framework; it is not a universal measure of a robot’s capability. Before interpreting a figure, find out which system was evaluated, what it had to do, and under what conditions the test took place. It also helps to separate what the report measures from what someone might merely infer from that measurement. A score makes sense when read together with the protocol that produced it.
This caution matters when results are presented as “better” or “more successful.” A difference between scores may reflect a difference between systems, but it may also reflect differences in tasks, objects, sensors, success criteria, or procedures. If evaluations do not share enough conditions, a ranked table cannot reliably attribute the difference to a single cause. It may still be useful to describe each result on its own; what becomes limited is direct comparison. A figure can look precise and still leave unresolved exactly what was compared. That is why comparison requires looking beyond the table’s order and checking which elements remained constant.
A research paper titled “Real-Time Systems Evaluation for Robotics Using the Hart-ROS Benchmark” addresses the evaluation of real-time systems for robotics using Hart-ROS. The title identifies its topic, but it is not enough to attribute findings to it about manipulation, generalization, or performance beyond the lab; supporting those claims would require examining its methods and results. Another paper proposes a puzzle-based robotic manipulation evaluation protocol that can be configured for different tasks and used at different levels of analysis. Read each score as an answer to a specific question, not as a verdict on the entire system.
Tasks and environments: measure the distance from intended use
Start with the task. Identify which actions the robot must complete, which objects are involved, how each attempt begins, and what conditions count as success. Also check whether the evaluation covers a single action or a complete sequence. A task may share a name with a real-world application and still differ in the range of objects, initial conditions, or tolerance for error. Judge similarity from what the protocol describes, not from the label alone. Reviewing these elements makes it possible to specify which part of the application is represented in the test and which part is not described.
Next, review the variations included in the environment. Do object position, appearance, or type change? Does the lighting or layout of the space vary? Are conditions different from those used to prepare the system tested? If the publication does not clarify these points, you cannot conclude that its result demonstrates robustness to them. That omission limits what the report allows you to claim; it does not prove that the robot will fail. Also distinguish variations that are part of the evaluation from those that might occur in the application: they are not equivalent. The question is which variations were actually tested, not which ones could be imagined from a general description.
The useful question is not whether a test seems realistic in the abstract, but which aspects of the scenario of interest it reproduces and which it leaves out. A controlled evaluation can help compare systems on a bounded ability without establishing how they will perform with different objects or changing conditions. Note that distance before using a score to make a practical decision. There is no need to dismiss a test because it is controlled; simply define the conclusion its design supports. A surface resemblance between a test and an application cannot replace a comparison of their conditions.
Metrics and protocol: understand what counts as success
A metric summarizes one dimension of an outcome, not necessarily every dimension that matters. A success rate may count how many attempts met a specified criterion. On its own, it does not necessarily report the time taken, interventions required, or consequences of failures. To assess a particular application, the success criterion and any additional measures should relate to the decision being made. If a study publishes only one aggregate figure, do not ask it to answer questions that figure does not contain. Read the metric’s definition before interpreting the name under which it is presented.
Check how many attempts were made and how they were prepared and reset. It matters what counted as an episode, whether tests were repeated, and whether results varied across repetitions. When these details are missing, it is not possible to reconstruct precisely how stable the estimate was. An average summarizes the available data; by itself, it does not guarantee that the result will recur in another session, with another team, or under different conditions. The number of episodes and the way they were run are part of interpretation, not mere procedural details. If the report provides information about variation between attempts, read that alongside the summary figure.
When comparing systems, look for shared conditions or a clear explanation of their differences. Check whether the same tasks, instructions, and rules for recording successes and failures were used. If the protocol changed, the comparison may still provide information, but the difference cannot automatically be attributed to the robot. A ranking ordered by score cannot repair incompatible protocols. When details are missing, specify which conclusion is limited rather than filling the gap with assumptions. This keeps the limitation visible and prevents it from being mistaken for evidence that one system is better or worse.
Simulation and hardware: distinguish evidence from extrapolation
A simulation test observes the system’s behavior under the conditions of that simulation. It is not, by itself, a measurement of a physical robot’s behavior. When comparing the two contexts, review what was evaluated in each, which conditions were held constant, and how the comparison was made. The key question is not only whether simulation was used, but what evidence the study presents to relate its results to those from real hardware. Identify separately what was observed in each context instead of assuming that one evaluation substitutes for the other. This distinction prevents an observation made only in simulation from being presented as a physical measurement.
One of the sources located is REALM, whose title describes a validated real-to-simulation benchmark for studying generalization in robotic manipulation. The title identifies the work’s general purpose, but does not by itself confirm which results it obtained or which specific conditions it verified. Similarly, knowing that a project addresses a relationship between simulation and reality is not the same as having enough evidence to conclude that a score simulates physical performance. To assess a particular case, examine its protocol and results.
The documentation available for this review does not allow us to describe in detail or validate a specific protocol for transferring from simulation to hardware. The caution therefore concerns the scope of the evidence we can establish here, not a general conclusion for or against such transfer. When reading a study, distinguish the proposed method from the evidence it offers about its ability to predict physical results. The aim of transferring results is not the same as demonstrating that they transfer.
Generalization: what an improvement allows you to claim
At a minimum, an improvement observed in a test allows you to say that the outcome of that evaluation changed under its conditions. Claims about generalization require tests that examine variations relevant to intended use and enough information to establish which variations were tested. Claims about operational usefulness also require measures that correspond to important aspects of that use, or relevant accompanying evidence. These conclusions are related, but they are not interchangeable. An improvement under one specific condition can therefore be informative without resolving whether it persists when relevant conditions change.
When reading a paper, record the task and success criterion; the robot and sensors; the environment and included variations; the metrics; the number of episodes; and the comparison rules. Then note what is missing and how that limits interpretation. This distinguishes absent information from a negative result: a factor not being described does not mean the system failed on that factor. Keeping a record also makes it easier to compare papers without erasing differences between protocols. If a feature is unspecified, mark it as unknown rather than treating it as a condition that was evaluated.
The sources consulted describe different benchmarking approaches, but they do not establish a general rule for how well results predict performance beyond the lab. This article therefore offers a way to read evaluations, not a ranking of tests or a guarantee about a particular method. Its value lies in making explicit the questions a score cannot answer on its own. A score is informative when its scope is known; to extrapolate, look for evidence that matches the scenario you care about.