The critical boundary: local privacy vs cloud
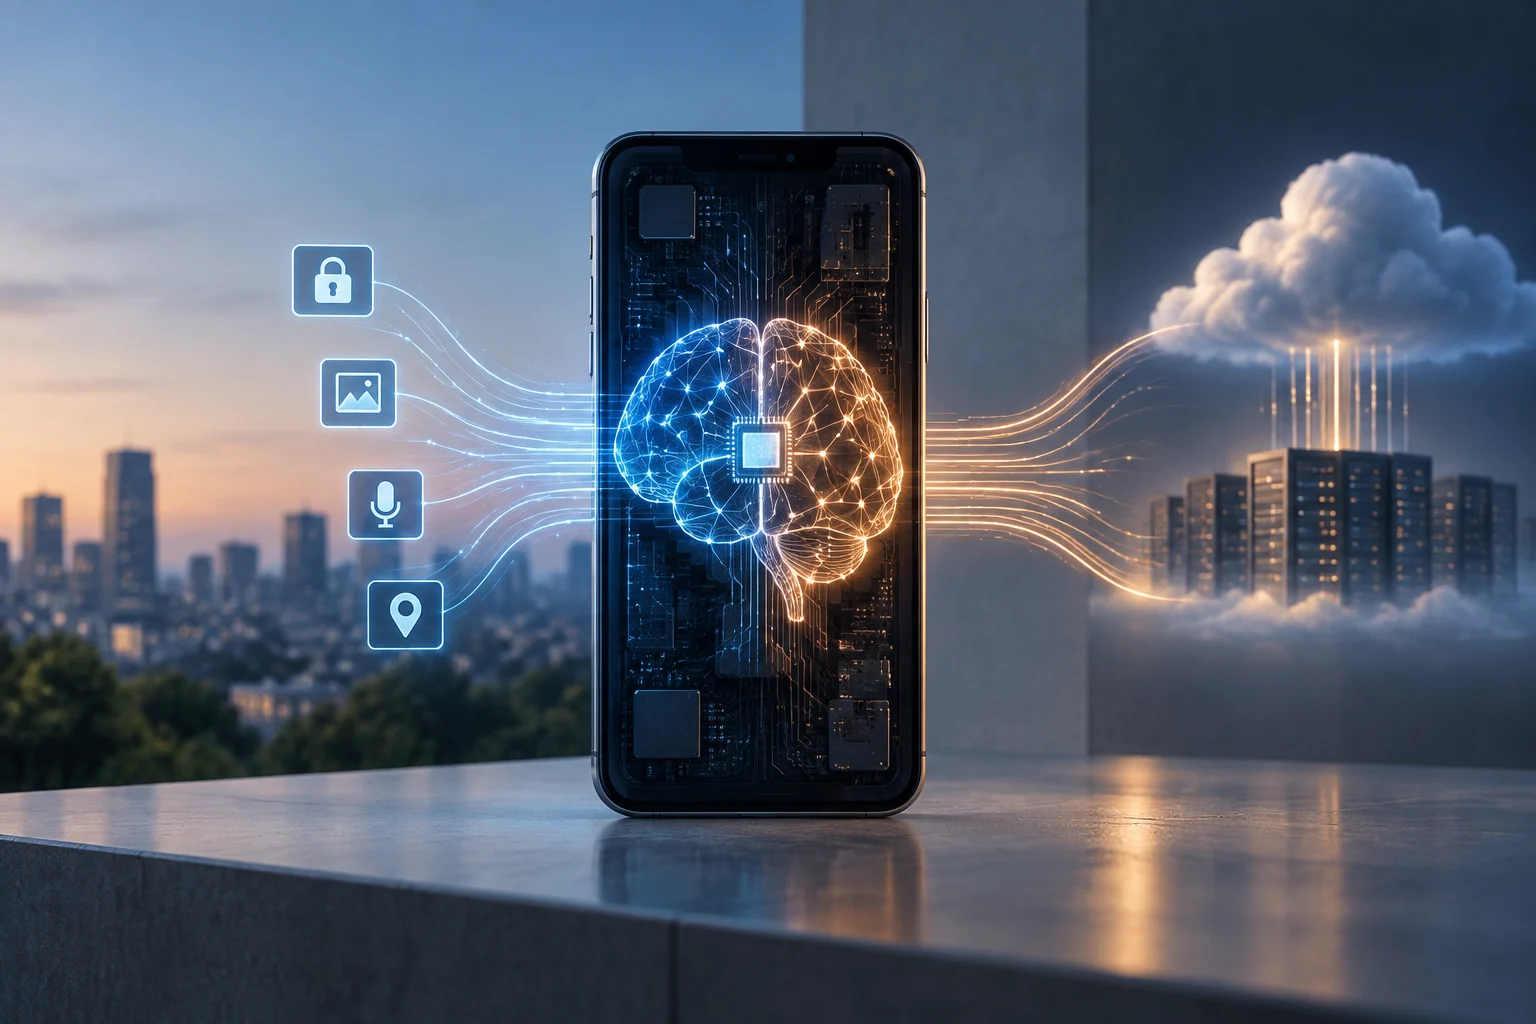
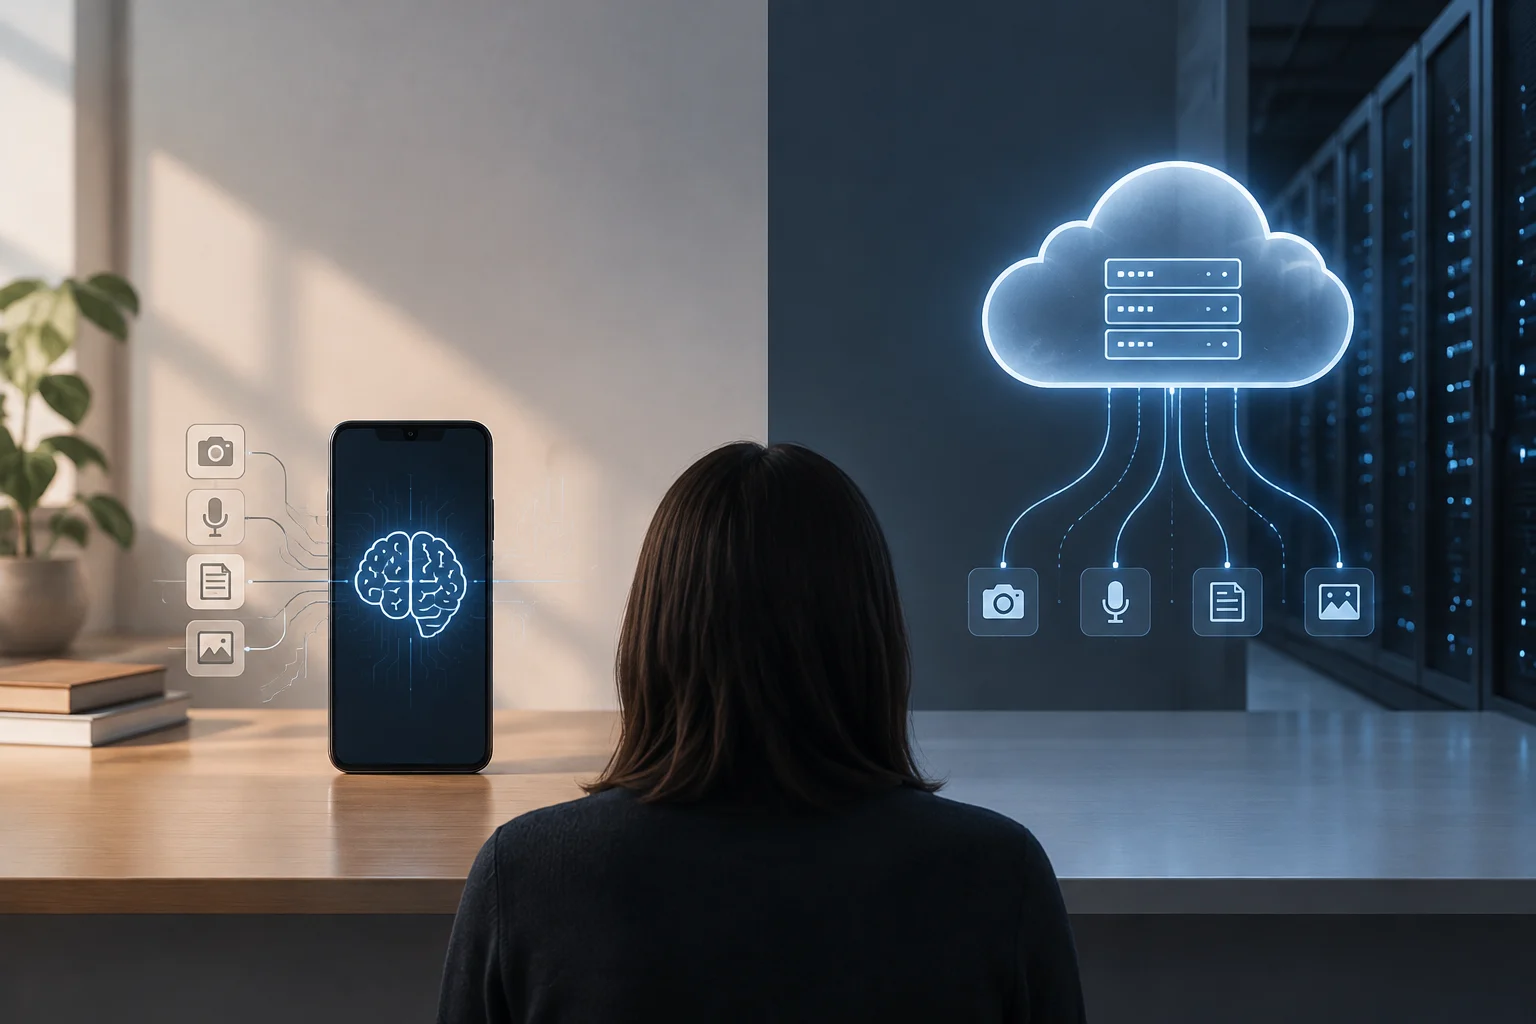
The fundamental distinction between a local AI application and a cloud-based one lies in where the model executes. In local processing, inference occurs within your hardware, meaning data never leaves the device. Conversely, cloud solutions send every query to remote servers, where it is processed and the response is returned.
This difference is not merely technical but concerns data sovereignty. According to specialized sources, local AI allows sensitive information to remain within the machine, reducing third-party exposure. However, it is crucial to understand that "local" does not always mean "offline": features like synchronization, billing, or updates may require network access even in local apps.
For the average user, this distinction determines the risk level. If you handle corporate, medical, or financial data, verifying the processing model is a mandatory security step before adopting any generative AI tool.
Step 1: Audit the application's official documentation
The first step to verify the origin of processing is to consult the developer's official technical documentation. Look for specific sections on "architecture", "system requirements", or "data privacy". Apps that run models locally usually specify the size of downloadable models and VRAM or RAM requirements.
In the case of tools like Ollama, LM Studio, or PocketPal AI, documentation clearly indicates that models are downloaded and executed on the device. In contrast, applications like ChatGPT or Gemini specify that processing occurs in the provider's cloud infrastructure, using services like Microsoft Azure or Google Cloud.
A key indicator is the presence of open-source models (such as Llama, Qwen, or Gemma) in the compatibility list. If the app allows loading local model weights, it is highly likely to offer a local inference option, though it often coexists with a cloud option for more powerful models.
Step 2: Analyze network and storage permissions
The permissions requested by the application on your operating system are a direct technical clue. A purely local AI app needs massive storage permissions to save model weights (which can occupy several gigabytes) and access to the GPU or NPU for inference.
Regarding the network, a local app ideally should only require a connection for the initial model download and updates. If the application requests constant network permissions and does not allow offline mode, it is likely sending data to the cloud. You can use network monitoring tools to see if there is constant outgoing traffic during inference.
It is important to distinguish between telemetry and data processing. Many local apps send performance metrics or errors to their servers, but not the content of your prompts. The privacy documentation must explicitly clarify what data is transmitted and for what purpose.
Step 3: Verify the device's hardware capacity
Not all hardware can efficiently run local AI. Local inference capacity critically depends on VRAM (video memory) and system RAM. For medium-sized language models, at least 8-16 GB of VRAM is recommended, while for small models, 4-8 GB may be sufficient.
If your device lacks a powerful dedicated GPU or sufficient RAM, it is technically unlikely that the app is running the model locally, unless it is a very small and distilled model. In mobile devices, the presence of an NPU (Neural Processing Unit) indicates that the manufacturer optimizes for local AI, as seen in ASUS, HP, or Lenovo devices.
You can verify your specifications in Task Manager (Windows) or System Information (macOS). If the app consumes significant GPU resources when responding, it is a strong signal of local processing. If the CPU and GPU remain inactive while the app responds, the work is being done in the cloud.
Step 4: Interpret the privacy policy
The privacy policy is the legal document that defines what the company does with your data. Look for clauses mentioning "model training" with user data. If the policy states that your prompts are used to improve the service, your data is leaving your device and being processed by third parties.
In local apps, the privacy policy is usually shorter and more specific: it states that data is processed on the user's device and not stored on central servers. However, it must clarify if usage metadata is collected or if there are synchronization features that could send data to the cloud.
An important nuance: some "hybrid" apps allow choosing between local and cloud. In these cases, the privacy policy must detail the conditions of each mode. If there is no clarity, assume the default mode is the highest risk, i.e., the cloud.
Practical decisions for data privacy
Based on verification, you can make informed decisions. If privacy is your top priority, choose apps that offer 100% local inference and verify that your hardware can support the models you need. Tools like Ollama or LM Studio are standard in this field.
If you need advanced capabilities your hardware does not support, consider using the cloud, but activate enhanced privacy options if the provider offers them (such as disabling training with your data). In corporate environments, tools like Sophos Protected Browser allow restricting file uploads in AI apps to prevent data leaks.
The key is technical transparency. Do not rely solely on "privacy" marketing; verify permissions, hardware, and documentation. An informed user can balance the convenience of the cloud with the security of local processing according to the sensitivity of each task.